Own the Verification: A New Execution Mindset for the Agentic Era
Picture an engineer reviewing an agent-generated pull request. It changes the payment client, retry configuration, tests, and deployment documentation. The engineer learned to work differently: follow the failing request through logs, reproduce the problem, edit each file, and build confidence one deliberate step at a time. Now the proposed solution is already on the screen.
The first reaction is not necessarily excitement or distrust. It might simply be: "That is not how I used to do this task." In this illustrative scene, the discomfort is not about whether the engineer can read the code. It is about the missing experience of having constructed it. A familiar route to understanding has been shortened, but understanding is still required.
That tension reaches well beyond software. When a tool produces work that used to demonstrate our expertise, we have to separate the method from the responsibility. The useful shift is neither "do everything yourself" nor "let the agent handle everything." It is a harder, more durable principle: embrace the leverage, own the verification.
When Muscle Memory Becomes a Measure of Worth
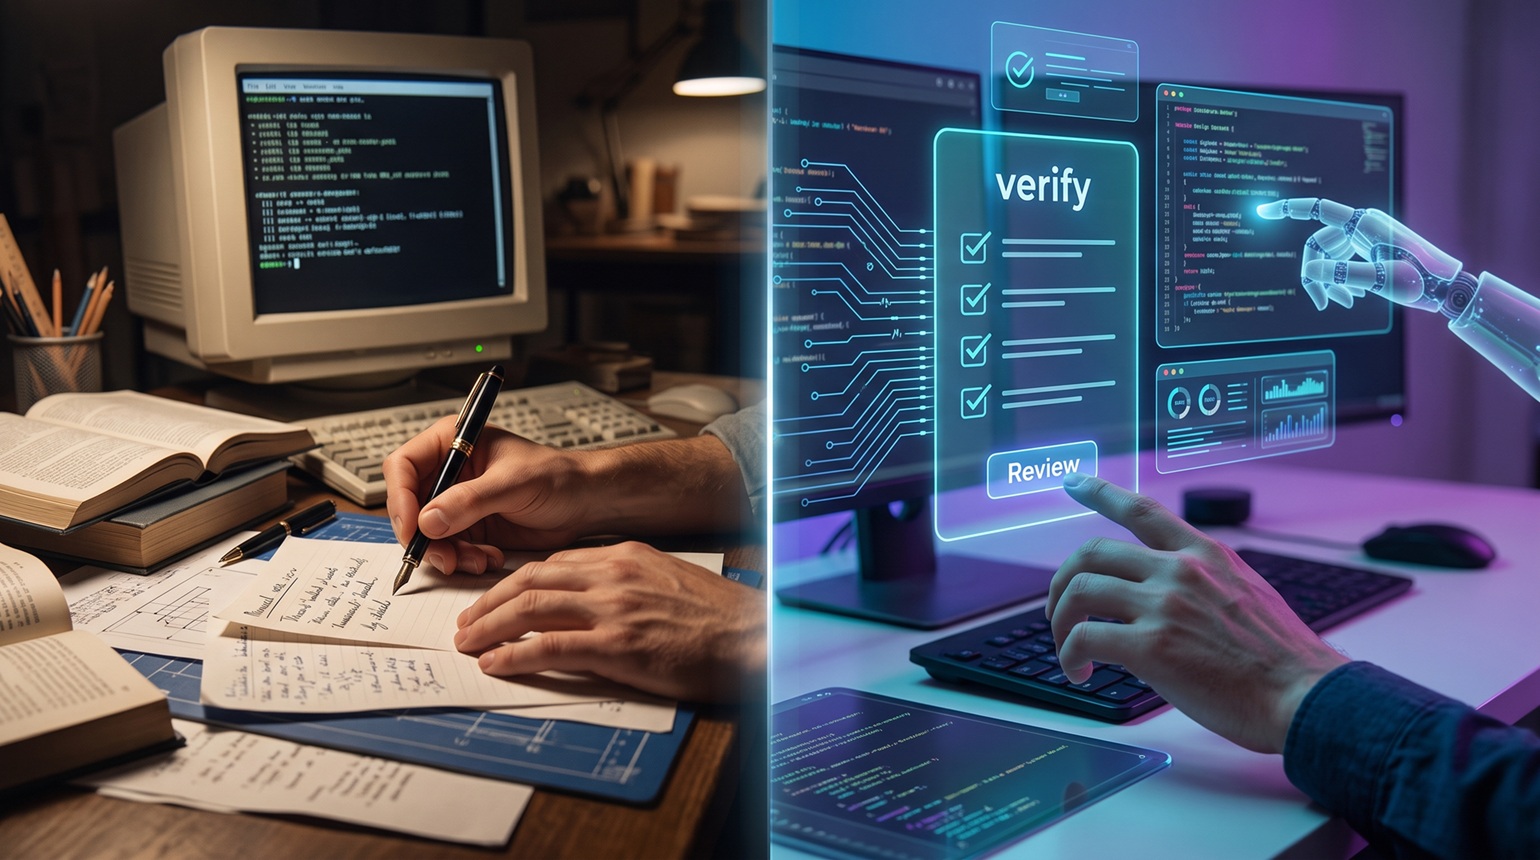
Manual execution taught valuable habits. Debugging a race condition builds an intuition for timing. Writing deployment configuration teaches how environments differ. Implementing an API exposes the distance between a tidy contract and an unreliable network. Those lessons do not become obsolete because a model can produce the next implementation.
But a useful habit can become an unnecessary rule: if I did not write every line, I did not really engineer the solution. Effort becomes a proxy for quality, and familiarity becomes a proxy for safety. Neither is reliable. A manually written change can be poorly understood; an agent-assisted change can be carefully specified and thoroughly verified.
This is about identity, not age. Someone early in their career may protect the coding skills they worked hard to acquire. An experienced engineer may welcome automation because they have already spent enough nights fixing repetitive mistakes. The dividing line is not a generation. It is whether we can update our methods without abandoning our standards.
Legitimate caution deserves a different response from resistance. "We cannot expose customer records to that tool" identifies a boundary. "We have no way to test this migration safely" identifies missing capability. "Real engineers do this by hand" identifies an attachment to a method. The first two call for a safer design or a decision not to delegate. The third calls for examining what the work is actually meant to achieve.
The goal is not to suppress discomfort. Use it to ask a better question: what evidence would let me trust this result, regardless of who or what produced it?
A Different Execution Model Requires Different Controls
An agentic workflow does more than complete a sentence. Depending on its permissions, an agent can inspect files, choose tools, propose a plan, modify code, run commands, and revise its approach. We are delegating parts of the route, not just asking for a faster keystroke.
Language models are probabilistic. Their outputs can vary, and a workflow can take different paths as context, tool responses, or model settings change. That does not mean every AI-enabled program is always nondeterministic. Constrained configurations can improve repeatability, and generated code may execute deterministically. The important point is that a successful run does not establish that the next agent run will make the same decisions.
Errors also arrive in convincing forms. A model may invent an SDK method, cite an outdated requirement, or preserve the happy path while subtly changing authorization. During a long task, context drift can push an earlier constraint out of practical focus. An agent asked to improve reliability may eventually optimize for making tests pass, even when that means weakening the test.
Humans make mistakes too. The issue is not that machine output deserves automatic suspicion while human output deserves automatic trust. It is that cheap, fluent production can multiply plausible mistakes faster than our existing controls can examine them.
Delegating 100% of an unguarded workflow is therefore an anti-pattern: an open-ended objective, broad credentials, no independent checks, and permission to release. Bounded autonomy is different. An agent can complete a well-defined task inside enforced limits, with evidence requirements and escalation points. The relevant question is not how many steps it performs alone. It is whether its authority matches the uncertainty and consequences.
Move Effort, Do Not Remove Judgment
The shift resembles earlier changes in abstraction. Moving from assembly to higher-level languages reduced the need to manage individual instructions. Moving from manually configuring servers to infrastructure as code made declared state reviewable and repeatable. Neither transition removed the need to understand memory, networking, access control, or failure.
The analogy has a limit. A compiler translates within a language's rules. Infrastructure tooling applies declared operations through specified mechanisms, although external systems can still fail or drift. An agent may choose which operations to perform and reinterpret an underspecified request. That extra discretion requires boundaries around decisions, not just validation of syntax.
The engineer becomes more of an orchestrator and verifier, but not merely a person who distributes prompts. The work shifts toward defining intent, resolving architectural tradeoffs, selecting trustworthy context, and deciding what evidence is sufficient. Sometimes the right orchestration decision is to write the difficult part yourself.
This can feel slower at the beginning. A clear specification costs thought before visible output appears. A realistic failure test costs more than accepting a green check. Yet those investments target the expensive uncertainty: whether the system will do the right thing when conditions stop being convenient.
The practical measure is not how little you touched the keyboard. It is whether you reduced total effort, including review, operation, and correction, without losing control of the outcome.
One Change, from Delegation to Release
Return to the payment pull request. Consider an illustrative service where a timeout prompts users to try again. An agent could add retries across several files quickly. That is useful only if the change does not charge someone twice.
Specify the Invariant Before the Implementation
"Make payments more reliable" is not enough. The owner defines the invariant: retries for the same logical payment must not create additional charges. The specification distinguishes a declined payment from a request whose outcome is unknown because the response was lost. A timeout does not prove the provider did nothing.
Before authorizing retries, the engineer checks the payment provider's actual idempotency contract: key scope, retention window, concurrency behavior, and how to retrieve an existing result. If the provider cannot support the required guarantee, an automatic retry may be the wrong design. The team must resolve that uncertainty, not ask the agent to invent a guarantee.
For this example, assume a documented provider contract supports the needed behavior. The plan requires a durable idempotency key per logical payment, reused across attempts and restarts, bounded retries only for eligible failures, and reconciliation of unresolved outcomes. It explicitly excludes changing authentication, adding a new provider, or redesigning the payment ledger.
Delegate a Bounded Slice
The agent gets the approved contract, relevant repository conventions, and a constrained task. It may modify the payment client, its retry policy, focused tests, and the operational notes. It may not access production credentials, alter deployment permissions, or deploy. Those limits belong in tool permissions and workflow enforcement, not only in a polite instruction.
The requested output includes a diff, assumptions, executed checks, and unresolved questions. If a schema change becomes necessary to preserve the key, the agent must stop and surface it. That is a productive escalation, not an execution failure. The human owns the architectural decision and can authorize a separate migration with its own controls.
Detect Problems Before Asking for Approval
The pipeline builds the changed code, runs existing regression tests, and checks for secrets, dependency changes, and edits outside the approved scope. Retry tests exercise exhausted attempts, cancellation, and an ambiguous timeout. Policy prevents the agent from changing those gates to make its own work acceptable.
These checks can detect problems, not establish complete correctness. A passing linter says little about duplicate charges. A test that mocks the provider as "timeout means no charge" can pass while validating exactly the wrong assumption. Detection has to target failure modes, not just produce a reassuring collection of green icons.
Review Decisions, Then Verify with Independent Evidence
The reviewer traces the payment identity across the client, persistence boundary, configuration, and tests. Does the key survive a process restart? Can two workers create different keys for the same payment? Is a retry limit applied at one layer but multiplied by another? Are logs useful without exposing sensitive payment data?
This review is about semantics and system boundaries. It deserves careful reading of the critical paths and affected contracts, not merely the agent's summary. If the summary claims that duplicate charges are impossible, the reviewer asks which documented guarantee and implementation mechanism support that claim.
Verification then looks beyond the author's assumptions. In a controlled integration environment, a fault is introduced after the provider accepts the payment but before the service receives the response. The service retries with the same identity. The team examines provider-side records and the internal ledger, checking for one logical charge and consistent reconciliation. Restart and concurrent-request scenarios test the same invariant.
A provider sandbox may not reproduce every production behavior, so its limits must be recorded. Existing contract tests, authoritative documentation, and an independently designed failure scenario provide stronger evidence together than a self-consistent implementation and test suite. Asking another agent to agree can help find gaps, but it does not by itself create independent evidence.
Release with a Recovery Plan
An accountable owner approves the bounded rollout. The team monitors duplicate-payment signals, unresolved outcomes, retry volume, and latency, with thresholds for disabling the new behavior. Support and operations know how to investigate an ambiguous payment.
Rolling back code does not undo a charge. Recovery therefore includes reconciliation and an approved process for correcting financial effects, not just a deployment button. The task is complete when the behavior and its operational consequences are understood, not when the pull request merges.
Accountability Must Fit Human Capacity
It would be easy to turn "own the verification" into "a human must read every line of every action." That does not scale, and it can make review ceremonial. A person approving more changes than they can understand is a named checkpoint, not an effective control.
Reviewer fatigue is a capacity problem as much as an attention problem. Keep changes coherent and small enough to reason about. Require useful evidence before review. Limit work in progress when the review queue grows. Producing ten more branches is not progress if the team cannot evaluate the first three.
Use risk-based gates. A constrained formatting change might pass deterministic checks and a policy-controlled automated merge. A payment retry change needs domain review and failure testing. Changes to access control or destructive infrastructure may require a second authorized approver. Risk classification itself needs enforceable rules and escalation; the producing agent should not be able to declare its own work harmless.
Human ownership lives at several levels: the person accountable for the change, the service owner accountable for operational behavior, and the leaders accountable for the delegation policy. Human-agent collaboration patterns help make those responsibilities explicit. "The AI did it" is not a useful incident explanation or a substitute for an owner.
Leaders must also fund the work they expect. Review time, test environments, observability, and training are part of adopting agents, not optional overhead. Evaluate delivery together with rework, escaped defects, recovery, and the ability to explain decisions. Reward an engineer for stopping an unsafe change, not only for getting another task through the queue.
Good policy makes autonomy adjustable. Expand it where evidence supports it; narrow it when failures reveal weak controls. Accountability does not require a person at every keystroke. It requires people who understand and maintain the system of permission, evidence, and intervention.
The Same Shift Reaches Almost Every Discipline
Software makes the mechanism visible because we can inspect a diff and run tests. But almost every discipline includes research, synthesis, drafting, planning, or decisions that AI can accelerate. The transferable principle is the same. The acceptable evidence, privacy obligations, and consequences are not.
Finance: Audit the Forecast, Not Just the Spreadsheet
Imagine an analyst asking an agent to prepare a cash-flow forecast. The workbook balances, the charts look sensible, and the narrative explains the expected shortfall. None of that proves the forecast reflects the business.
The analyst traces inputs to approved financial systems, checks periods and currencies, and distinguishes booked revenue from cash actually expected to arrive. They examine assumptions about collection delays, renewal rates, and one-time expenses. A plausible forecast can be materially wrong because a formula includes an internal transfer as new cash.
Independent verification might include reconciling opening balances with the ledger, recalculating critical formulas outside the generated workbook, and comparing scenarios with actual historical outcomes. The decision owner also asks whether assumptions remain valid under current conditions. Let the agent assemble and explore; do not let an attractive narrative silently choose the organization's financial assumptions.
Clinical Work: Verify the Summary Against the Record
Consider a clinician using an approved system to draft a diagnostic summary from a patient's record. This is an illustrative workflow, not medical advice. Identifiable information must stay within an authorized environment with appropriate privacy, access, and retention controls.
The clinician checks the summary against the original notes, laboratory results, medication history, and relevant dates. Was a suspected condition presented as confirmed? Was an old medication described as current? Did the summary omit an allergy or flatten conflicting observations into a confident statement?
The value is faster preparation, not permission to outsource clinical judgment. The clinician must assess the patient and the relevance of the evidence, resolve uncertainty, and follow professional and institutional requirements. A fluent summary is not a diagnosis, and another model's endorsement is not a clinical validation.
Legal Work: Open the Sources
A lawyer can use an agent to organize an argument or draft a research memo. Verification requires opening the actual authorities, confirming that cited cases exist, and checking that quotations and holdings support the proposition. Jurisdiction, procedural context, and whether an authority remains applicable all matter.
A citation that looks authentic is only a lead until it is checked. Confidentiality and approved-tool policies also apply before material is supplied to the system. The lawyer remains responsible for the advice and filing, including omissions that make an otherwise accurate paragraph misleading.
Creative and Operational Work: Verify Intent and Consequences
A designer can explore more directions with generated concepts, but must still evaluate originality, usage rights, accessibility, and fit with the brief. A polished campaign may repeat an unsupported product claim or communicate something the organization never intended to promise.
An operations planner can delegate a draft staffing schedule while checking labor constraints, actual availability, and coverage during handoffs. Before changes reach employees, the planner verifies the source data and the effects on people whose circumstances may not be represented in the spreadsheet.
These are not equivalent risks. A weak visual concept, a financial misstatement, and an unsafe clinical decision demand different safeguards. What transfers is the separation of production from acceptance: embrace the leverage, own the verification.
Keep the Fundamentals, Change the Measure of Craft
Verification without domain knowledge quickly becomes a ritual. Engineers still need to debug, read unfamiliar code, reason about distributed systems, and understand security boundaries. As the case for fundamentals before AI explains, understanding is what makes the output evaluable in the first place.
Preserve that ability deliberately. Reproduce difficult failures, implement small experiments, and occasionally solve a bounded problem without assistance. Use agents to propose competing explanations, then test them. For learners, alternate assisted work with explaining and rebuilding the critical parts. The aim is retained competence, not manual purity.
Nor should "orchestrator" become a status upgrade that makes hands-on work somebody else's concern. If you cannot investigate a failed result, you cannot responsibly supervise it. Sometimes opening the debugger is the shortest path to evidence. Sometimes a well-bounded delegation is. Mature practice can use both.
Return to the engineer looking at that multi-file pull request. "That is not how I used to do this task" can remain true without becoming an objection. The next questions are more useful: what did we authorize, what could be wrong, and what evidence supports release?
The engineer may accept the change, request a smaller one, or reject the approach. All three can be good engineering. The accomplishment is not that an agent did the work, or that a human refused its help. It is that someone still owns whether the work deserves to be trusted.